Five read-only health checks
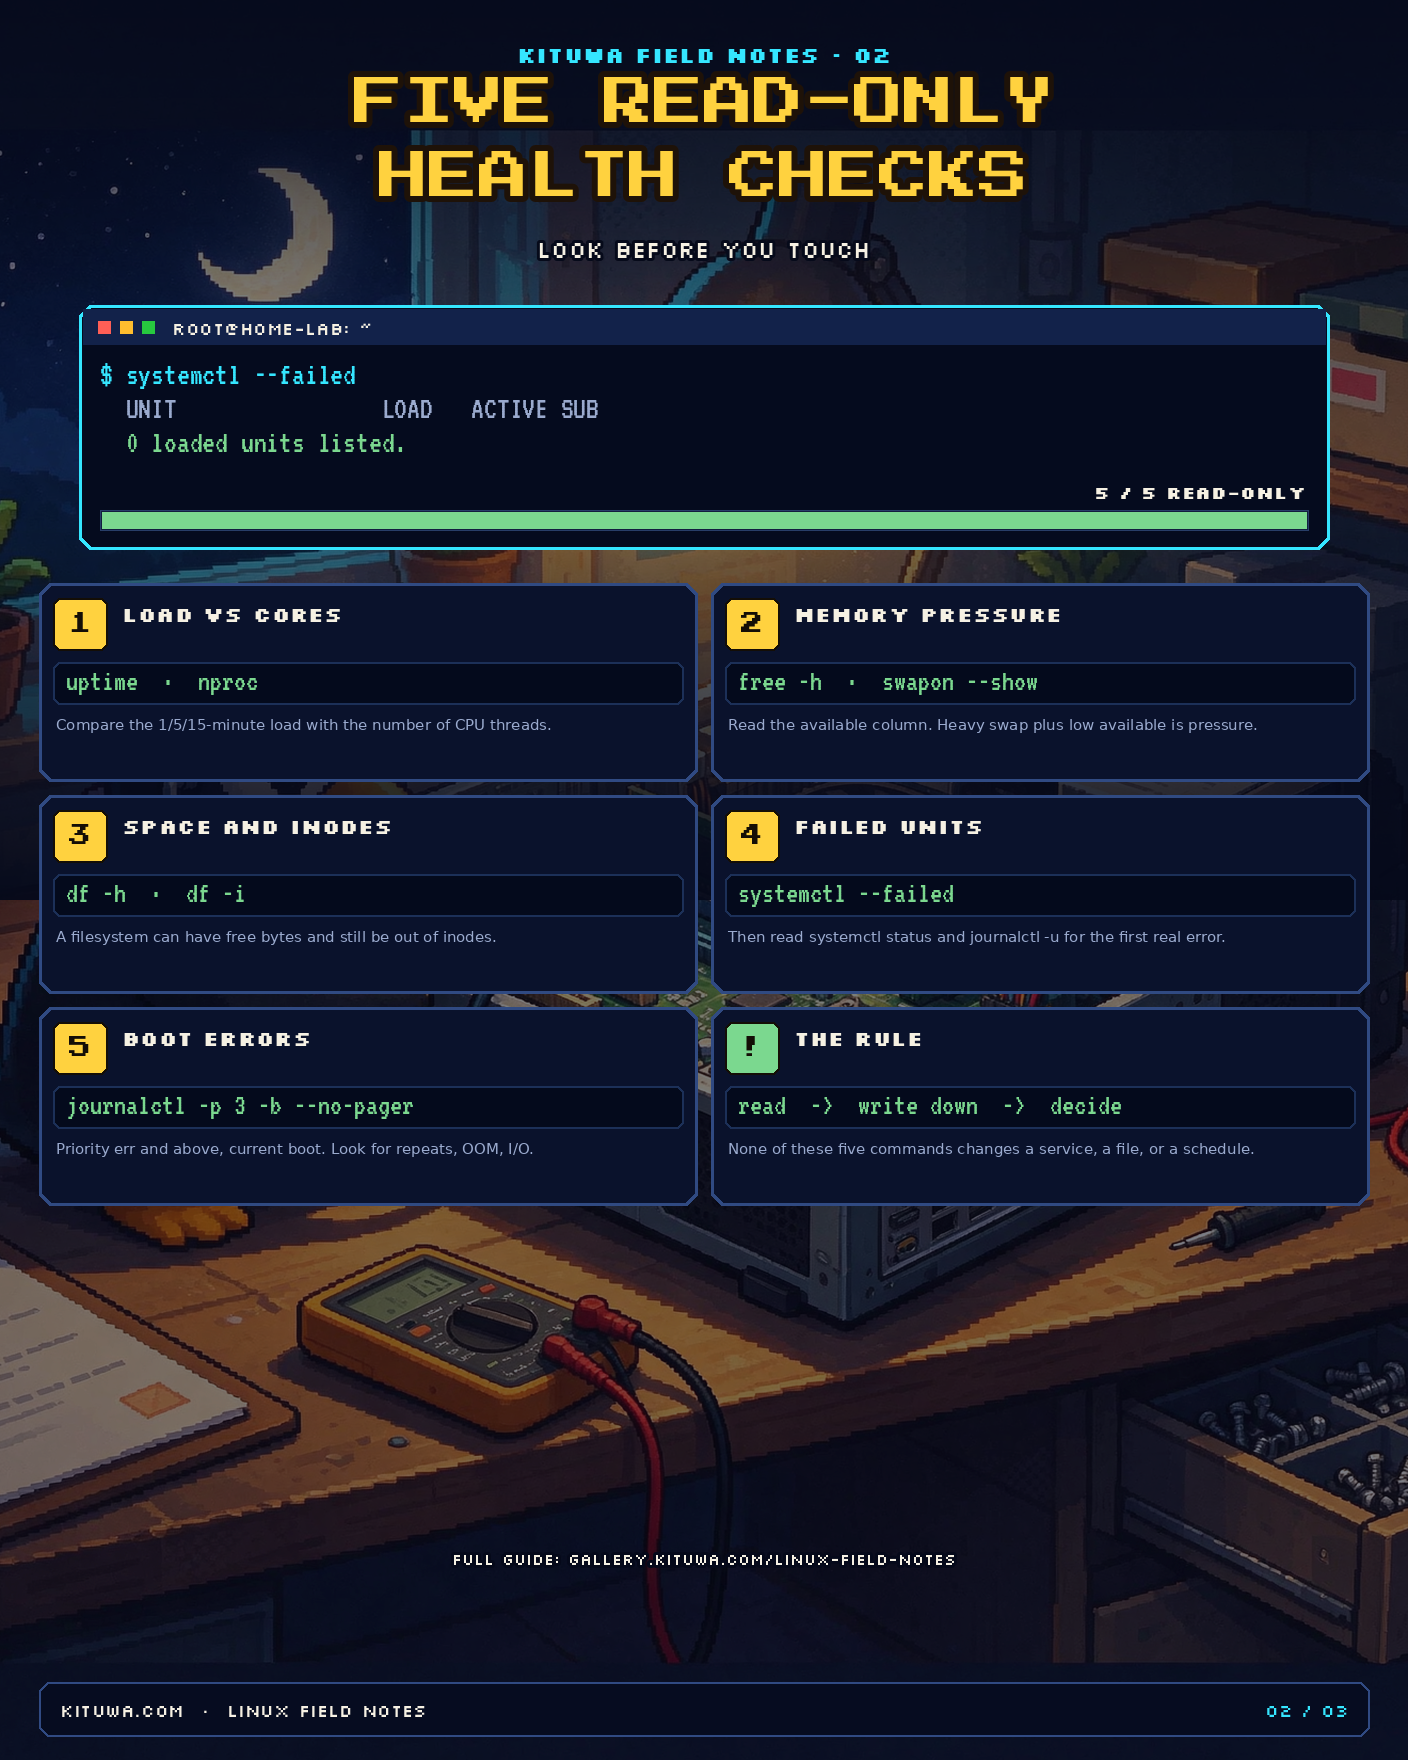
When a server feels slow, the dangerous move is to start changing things before you know what is wrong. These five commands only read state. They do not write to disk, restart a service, or change a configuration file. Run them in order, write down what you see, and only then decide what to fix.
1. How busy is it, really?
uptime
nproc
uptime prints the load average for the last 1, 5, and 15 minutes. nproc prints the number of CPU threads. Compare the two: a load of 8 on a 4-core machine means roughly twice as much runnable work as the CPU can handle. A load of 8 on a 16-core machine is unremarkable.
Look at the trend, not one number. A 1-minute spike is a backup or a build. A 15-minute load that stays above the core count is a queue.
2. Is memory pressure real?
free -h
swapon --show
Read the available column, not free. Linux uses spare RAM for cache, so free is often small on a healthy machine. available estimates what a new process can use without swapping.
Then look at swap. A little swap in use is normal. A lot of swap plus a low available value means the machine is under memory pressure. swapon --show tells you which swap devices exist and how much is used.
3. Is it disk space or inodes?
df -h
df -i
df -h shows each mounted filesystem. A full /var, /home, or Docker volume can break a service even when / looks fine. df -i shows inode usage. A filesystem with free bytes but 100% inodes cannot create new files; millions of tiny files will do that.
Check the Use% and Mounted on columns together. Do not assume the full filesystem is the one you are looking at.
4. Did a unit fail?
systemctl --failed
This lists systemd units in the failed state. It is a fast way to catch a crashed service that is not obvious from the application logs.
For each failed unit:
systemctl status example.service
journalctl -u example.service -n 50 --no-pager
systemctl status shows the exit code and the last few log lines. journalctl -u gives more context. Read the first error, not the last one; later errors are often consequences.
5. What is erroring this boot?
journalctl -p 3 -b --no-pager
-p 3 means priority err and above. -b limits the output to the current boot. This is a broad scan, so expect noise from services you do not use. The goal is to find repeating errors, OOM kills, filesystem errors, or a driver failing in a loop.
If the output is huge, narrow it:
journalctl -p 3 -b --no-pager | tail -100
journalctl -p 3 -b --no-pager | grep -i -E "error|fail|oom|denied"
Reading the result
| Check | Green | Yellow | Red |
|---|---|---|---|
| Load vs cores | load below cores | brief spikes | sustained above cores |
| Memory | available is healthy |
some swap | low available, heavy swap |
| Disk | under 80% | 80–90% | over 90% or inodes full |
| Failed units | none | one known failure | several or a critical unit |
| Boot errors | none repeating | known noise | OOM, I/O, or filesystem errors |
What not to do
Do not run systemctl restart on everything. Do not clear logs to make the error disappear. Do not delete files before you know which process owns them. The five checks above are cheap; a bad “fix” is expensive.
A note on context
A container can look healthy from the host and still be out of memory inside its cgroup. If the host checks are green but one service is struggling, inspect that service's own limits and logs. The host view is the first layer, not the only layer.
Share this
 Scan to open this page on a phone.